unique_ptr with an empty lambda deleter stays 8 bytes; a function-pointer deleter doubles it to 16

A unique_ptr With a Custom Deleter That Costs Zero Bytes

Wrapping a C handle in unique_ptr with a function-pointer deleter doubles the pointer to 16 bytes. Putting the function into the deleter type instead, with an alias template over decltype of a static lambda, brings it back to 8. Sizes checked on GCC 14.2, GCC 16.2, Clang 22.1 and MSVC 19.44, with live Godbolt sessions.
October 20, 2026 · 4 min · Pavel Guzenfeld
Building a {}{}{} format string at compile time with a loop, ranges, and an index_sequence fold

Building a "{}{}{}" Format String at Compile Time, Three Ways

A variadic concat(args…) that builds its own “{}{}{}” pattern at compile time, written three ways: a plain loop, a ranges pipeline, and an index_sequence with a comma fold. fmt 12 and std::format both still check the generated pattern at compile time, but only if it is static constexpr. Verified on GCC 14.2, GCC 16.2, Clang 22.1 and MSVC 19.44.

October 20, 2026 · 5 min · Pavel Guzenfeld
Converting a GStreamer buffer PTS plus base_time into a std::chrono::steady_clock time point

From GStreamer PTS to std::chrono::steady_clock

A buffer’s PTS is running time, not wall time. Add the pipeline’s base time and you get the clock time the frame was captured at. With the monotonic system clock that is a std::chrono::steady_clock time point you can compare to IMU or telemetry timestamps directly.

October 20, 2026 · 7 min · Pavel Guzenfeld
A bump arena allocates a frame of 1000 objects about 10x faster than malloc and free

ZII and Arena Allocators in C++: Zero Is Initialization, Benchmarked

ZII designs every type so all-zero bytes is a valid default, and pairs it with arenas that free a whole group at once. RAII ties cleanup to each object. Here is how the two differ, where ZII falls short, a 20-line arena, and a nanobench run of 1000 allocations per frame: arena, std::pmr, malloc, calloc and new, with a live Godbolt session. Plus a struct-of-arrays layout, a Cortex-A78AE run, and the Jetson Orin GPU, then one CPU+GPU frame that uses all of it: 3.3x faster per frame.

October 20, 2026 · 27 min · Pavel Guzenfeld
Zero-copy GStreamer tracking pipeline on Jetson Orin

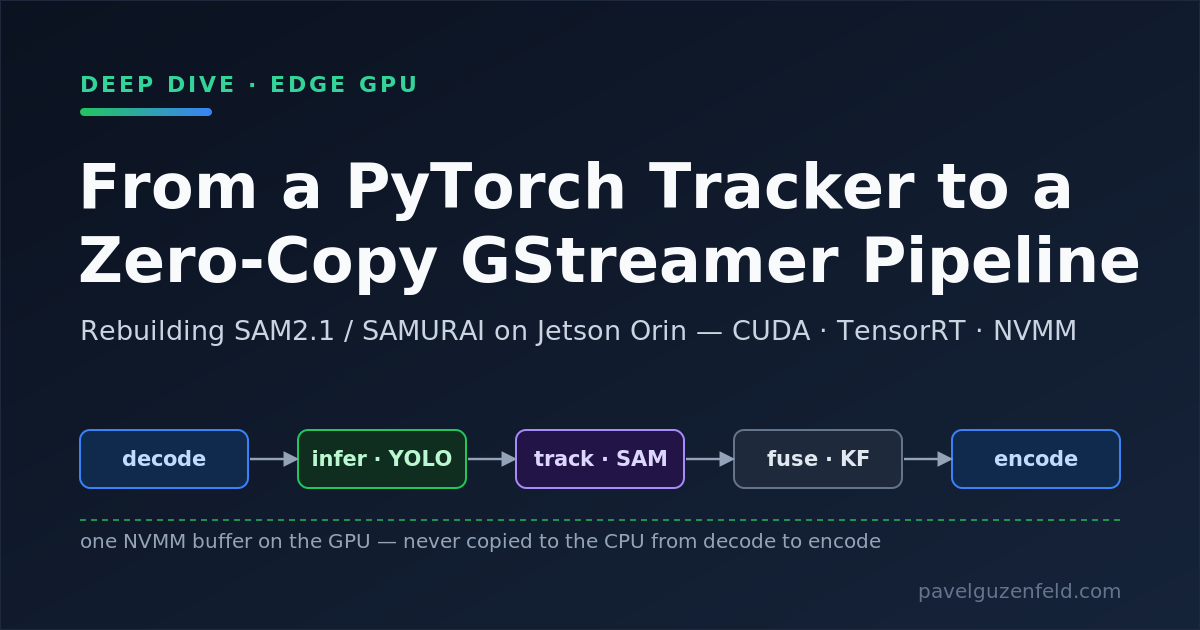
From a PyTorch Tracker to a Zero-Copy GStreamer Pipeline: Rebuilding SAM2.1/SAMURAI on Jetson, Step by Step

A long, hands-on account of turning a research-grade PyTorch visual tracker (SAM2.1 / SAMURAI) into a real-time, zero-copy GStreamer + CUDA + TensorRT pipeline on a Jetson Orin NX — decomposing the model into engines, exporting and parity-validating each one, porting the per-frame math to CUDA, packaging it as a GStreamer element, and squeezing 8 fps into 24 with queues and frame-skipping. Every stage is validated against a golden reference.

June 15, 2026 · 20 min · Pavel Guzenfeld
The Road to Boost.SML 1.2.0

The Road to Boost.SML 1.2.0: New API and a Type-Name Heisenbug

A warts-and-all account of cutting the Boost.SML 1.2.0 release — four new public APIs, a behavior change rooted in undefined behavior, a type-name Heisenbug that only fired on GCC and MSVC, a dead “Run” button, and the surprisingly deep rabbit hole of making 30 Compiler Explorer links that actually work.

June 1, 2026 · 14 min · Pavel Guzenfeld
C++ State Machine benchmarked — switch/case vs GoF unique_ptr vs C++23 variant/visit

C++ State Machine, Three Ways: Switch/Case, GoF unique_ptr, and C++23 Variant — Benchmarked

Three implementations of the same aircraft lifecycle FSM — a switch/case flat machine, the classic GoF State pattern with unique_ptr, and a C++23 compile-time variant/visit design — compiled with GCC 14 at -O2 -std=c++23, measured with nanobench, and linked to four live Godbolt sessions. The headline numbers: for a full seven-event mission cycle, the variant approach is 6× faster than OOP and switch/case is essentially free (the optimizer evaluates the constant-input trace at compile time). On the steady-state telemetry hot path, switch runs at 0.56 ns/event, variant at 1.07 ns/event, OOP at 1.20 ns/event. The culprit is not virtual dispatch — it is heap allocation. A follow-up section adds get_if chains and the [[likely]] attribute: on single-variant dispatch all four strategies land within 0.11 ns.

May 23, 2026 · 14 min · Pavel Guzenfeld
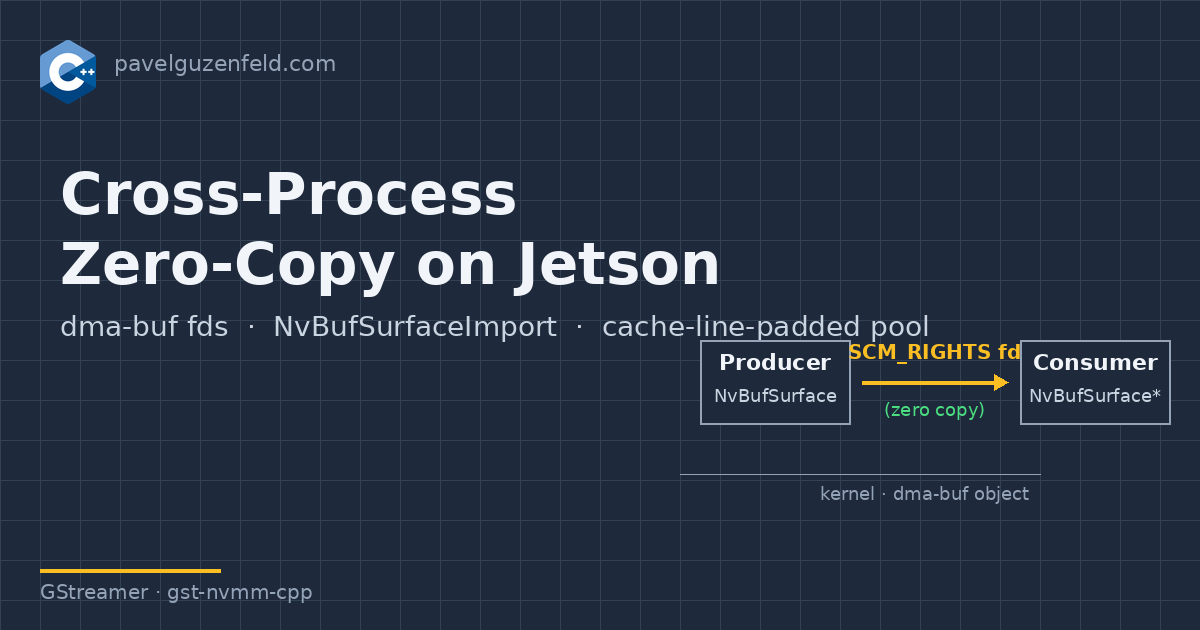
Cross-process zero-copy NVMM IPC on Jetson — dma-buf fd passing, NvBufSurfaceImport, lock-free pool

Cross-Process Zero-Copy on Jetson: dma-buf fds, NvBufSurfaceImport, and a Cache-Line-Padded Pool

Two processes on a Jetson, one camera frame in NVMM (GPU memory), no copies. The kernel does the heavy lifting via dma-buf fds; SCM_RIGHTS carries the fd across the process boundary; NvBufSurfaceImport reconstructs the surface on the consumer side; a cache-line-padded ring of atomic ref-counts keeps fan-out coherent without locks. With benchmark numbers and a Godbolt-runnable demo of the SCM_RIGHTS pattern.

April 25, 2026 · 22 min · Pavel Guzenfeld
C++ low-latency patterns benchmarked — HFT, cache-friendly layouts, and the tricks that don't reproduce

C++ Low-Latency Patterns, Benchmarked: 15 Tricks from HFT and CppCon 2025 (and Which Claims Don't Reproduce)

Fifteen C++ performance patterns from three sources — Bilokon & Gunduz’s HFT paper at Imperial, Jonathan Müller’s Cache-Friendly C++ deck at CppCon 2025, and Okade & Baker’s C++ Performance Tips at CppCon 2025 — implemented as single-file nanobench programs, run under Docker on GCC 14 with -O2 -std=c++23, every one of them linked to a working Godbolt session. The surprising half: three of the ’textbook’ speedups do not reproduce on a modern CPU. Cache warming is 7x slower than cold. Bitmask branch reduction is slower than the cascade it replaces. This post is the full runbook, numbers included, with the nuance that explains when each pattern actually earns its keep.

April 23, 2026 · 28 min · Pavel Guzenfeld
C++ tools that enforce low-latency patterns — builtins, compiler flags, clang-tidy checks

C++ Low-Latency, Enforced: __builtin_*, Compiler Flags, and clang-tidy, Benchmarked

Follow-up to the 15-pattern HFT post. The first post asked ‘which patterns work?’ This post answers ‘how do you force your team to keep using them?’ Seven new nanobench programs, each with a working Godbolt link, covering __builtin_popcountll (24x faster than a bit-count loop), __builtin_unreachable in switch defaults (1.55x), __builtin_bswap64 (same speed as the portable idiom — GCC already folds it), [[likely]] and [[unlikely]] (no measurable effect on tight loops — an honest null result), and a flags matrix showing -ffast-math + -march=x86-64-v3 giving 6.9x over -O2. Then a .clang-tidy config that fails CI on every common perf regression, with the performance-for-range-copy warning demonstrated at 41x real runtime cost.

April 23, 2026 · 21 min · Pavel Guzenfeld